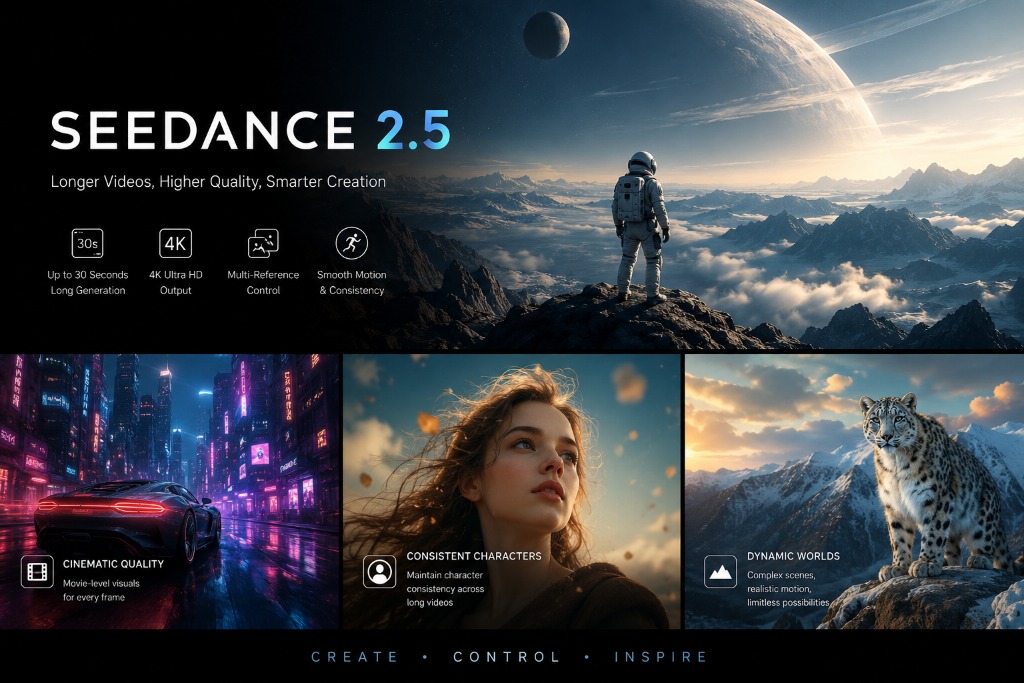
Seedance 2.5: One-take Creation, Flexible Referencing
A next-generation audio-video joint generation model for 30-second storytelling, stronger multimodal referencing, and precise editing.
Research Scientist, Seed, ByteDance
I am currently a Research Scientist at ByteDance Seed, where I work on RLHF for video generation and contribute to the development of Seedance 1.5, Seedance 2.0, and Seedance 2.5.
Previously, I worked at Meituan M17, a multimodal foundation model team, where I led work on the RoboTron series for autonomous driving and embodied AI, including RoboTron-Drive, RoboTron-Sim, RoboTron-Mani, and RoboTron-Nav.
Earlier, at Malong Technologies, I worked on object detection and led TOOD, a task-aligned one-stage object detector that has been widely adopted in the YOLO family, including PP-YOLOE, YOLOv6, YOLOv8, YOLOv10, and YOLO-World.
A next-generation audio-video joint generation model for 30-second storytelling, stronger multimodal referencing, and precise editing.
A native multimodal audio-video generation model supporting text, image, audio, and video inputs with stronger controllability.
A native audio-visual joint generation foundation model with improved lip-syncing, cinematic camera control, and narrative coherence.
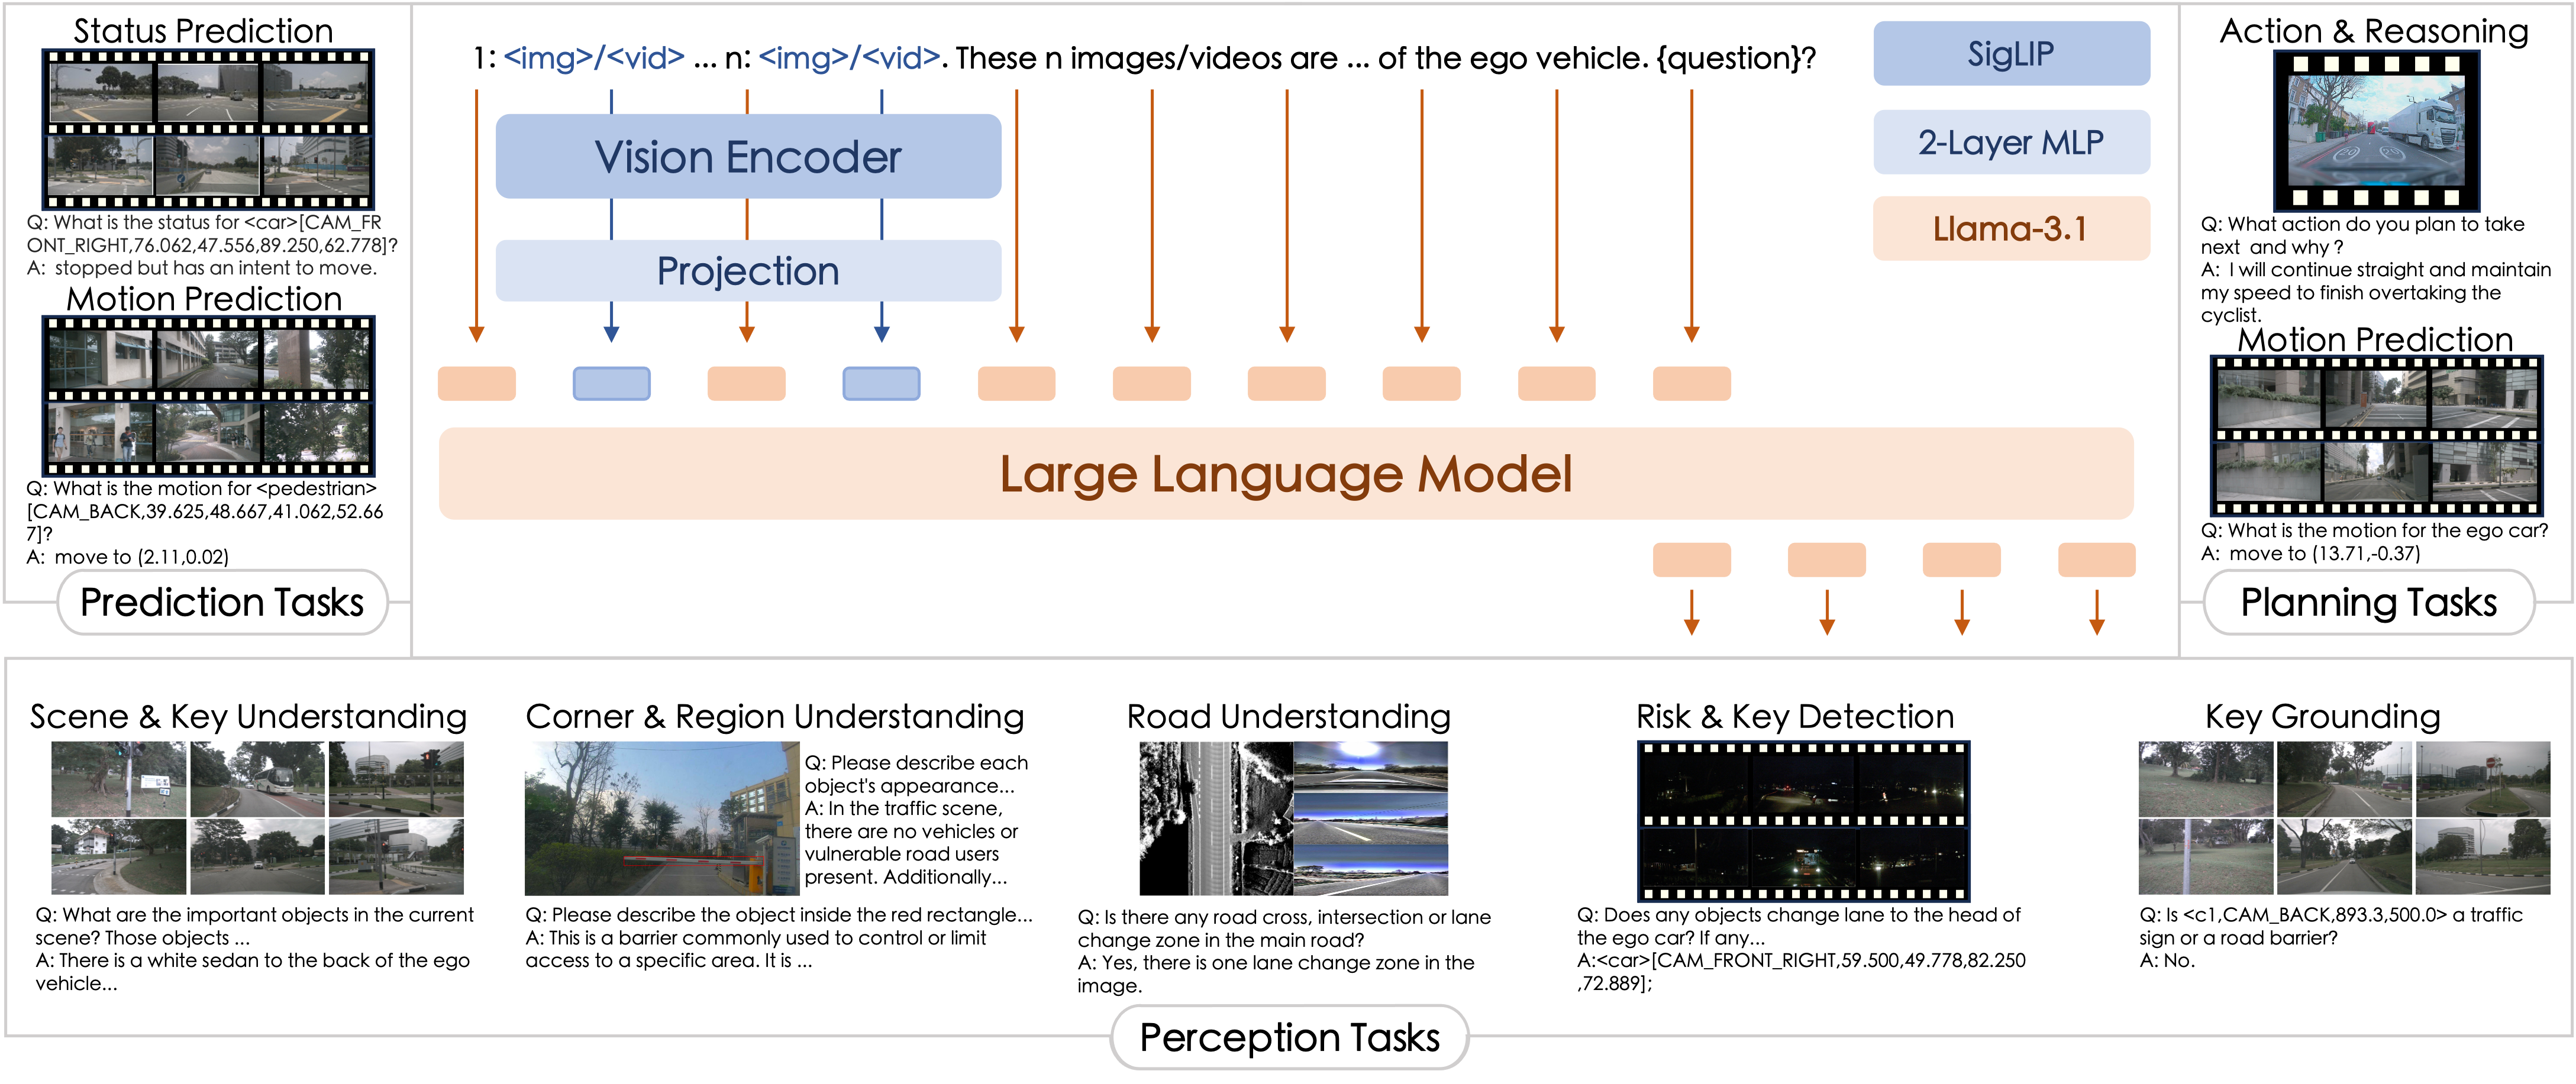
An all-in-one large multimodal model for autonomous driving with general capabilities and strong generalization across driving tasks.
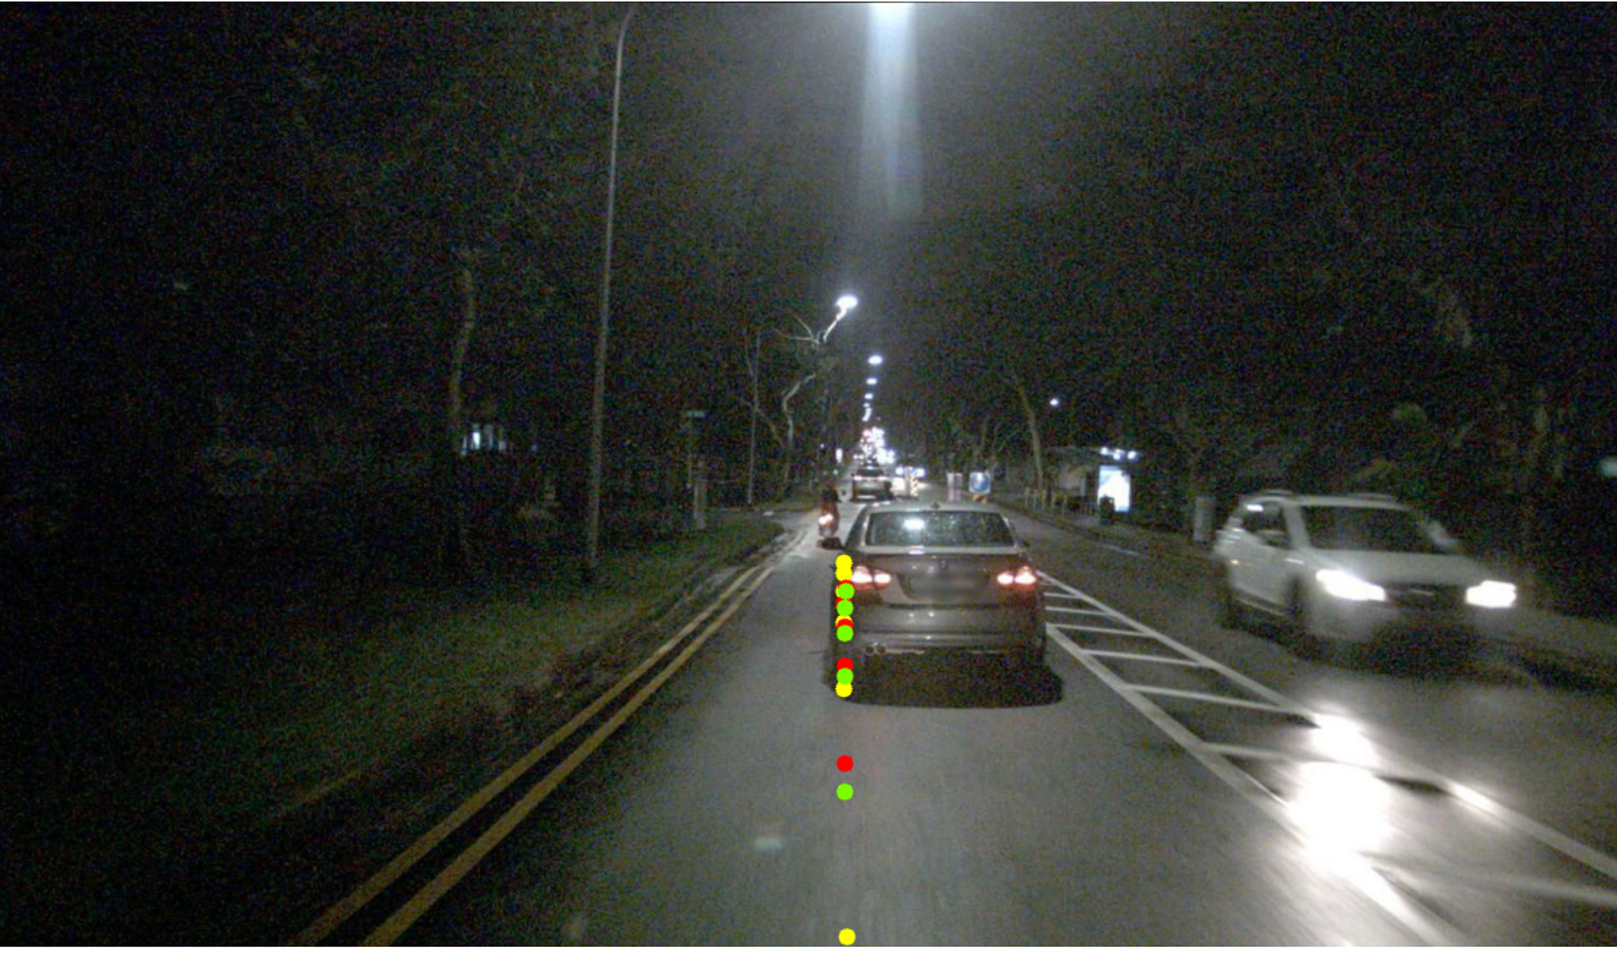
A simulation-based framework that improves real-world driving performance by learning from simulated hard-case scenarios.
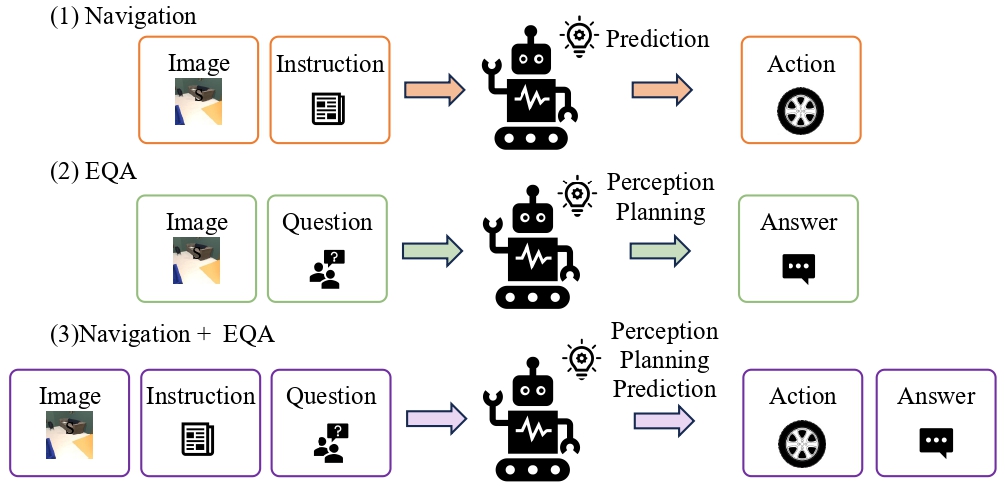
A unified embodied navigation framework that integrates perception, planning, and prediction for navigation and embodied question answering.
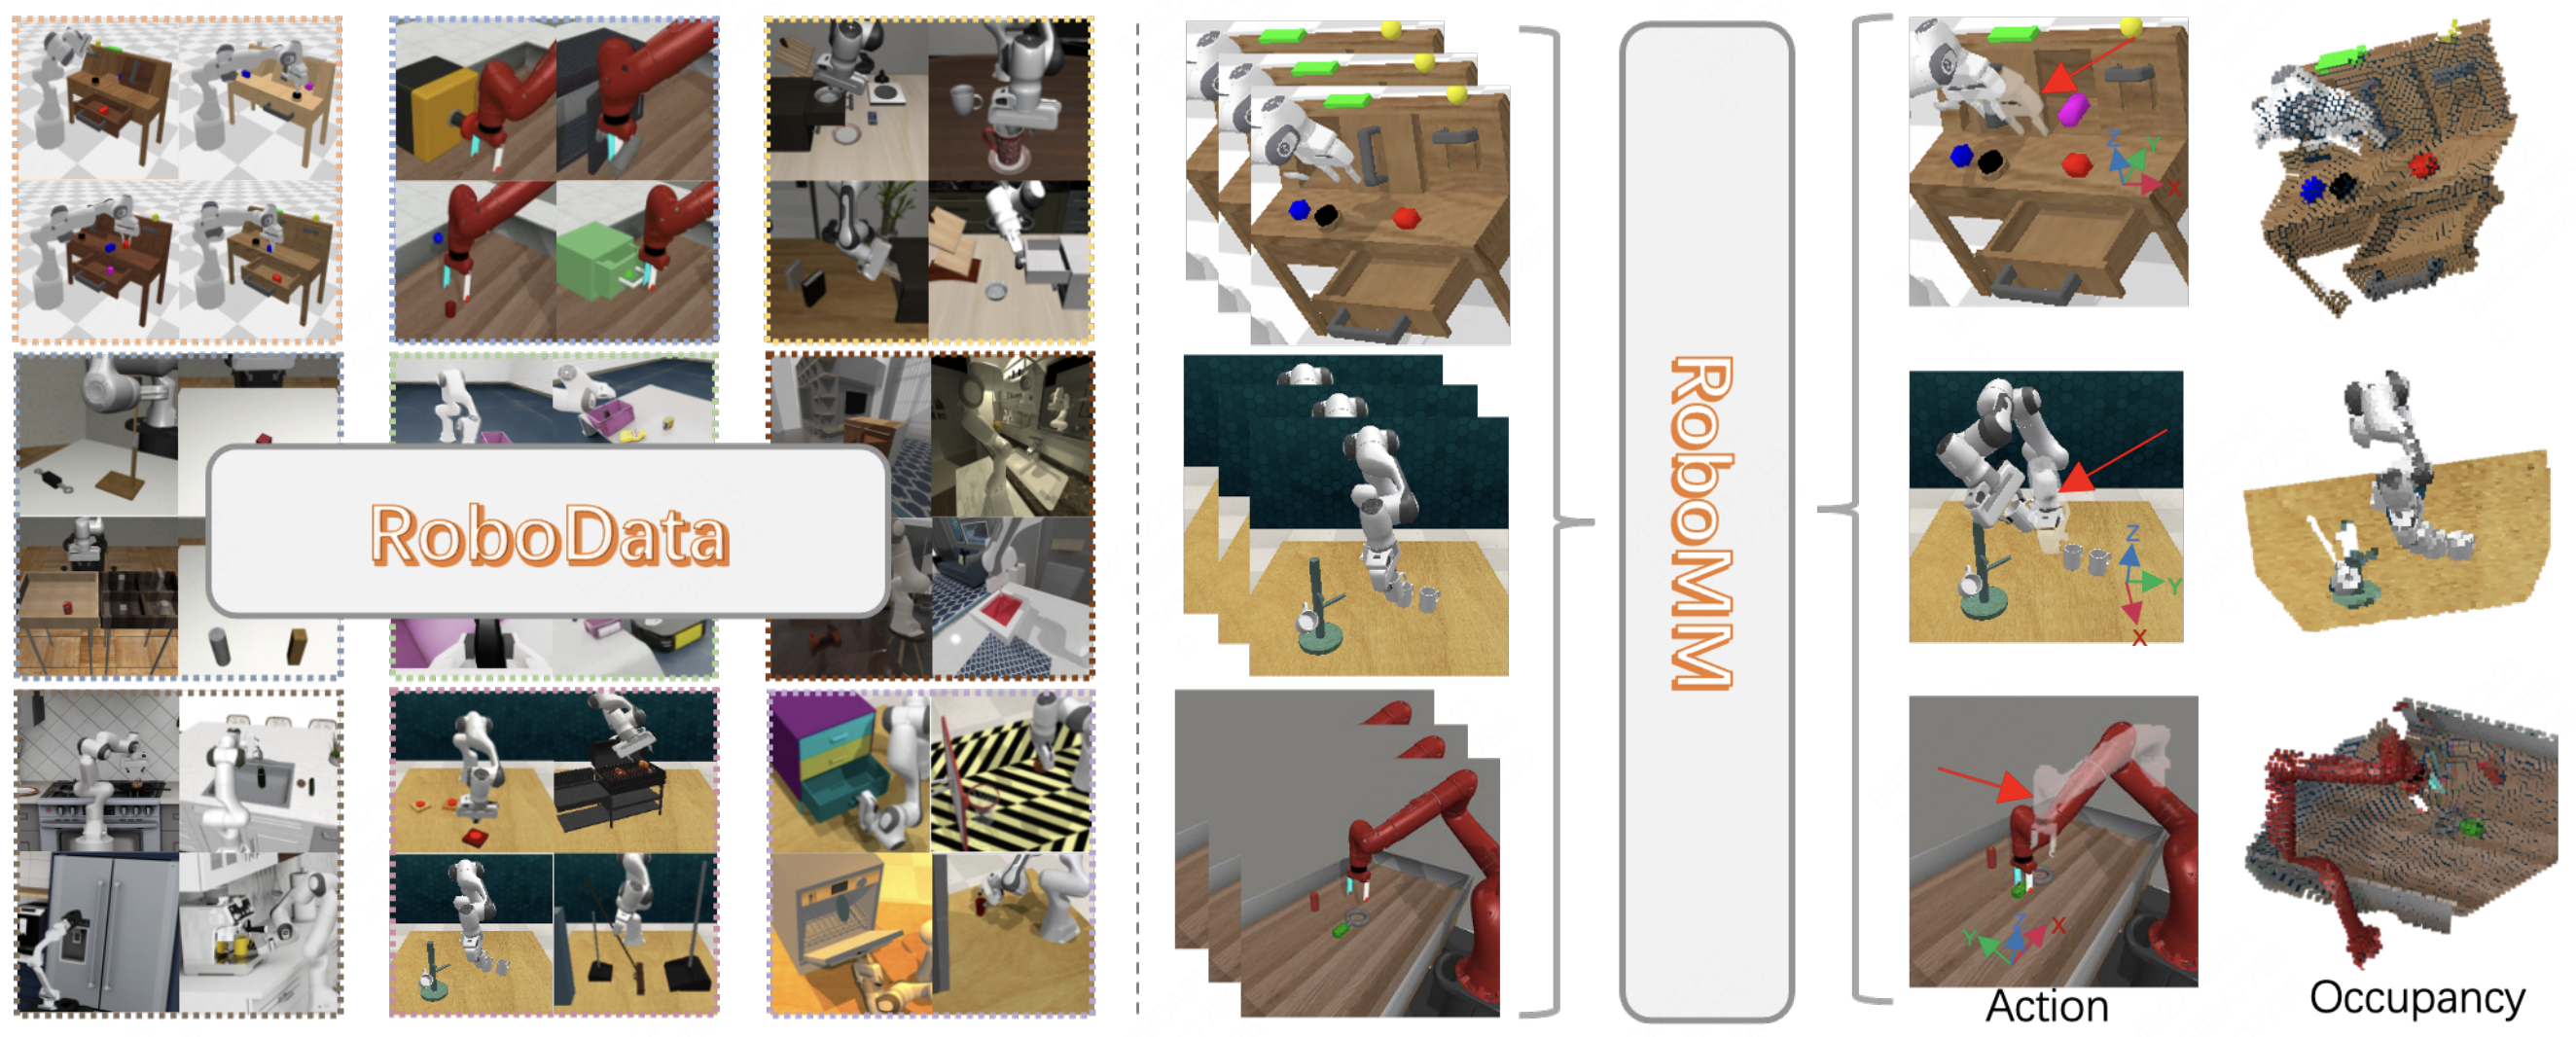
An all-in-one multimodal model for robotic manipulation with 3D perception, action prediction, and cross-embodiment generalization.
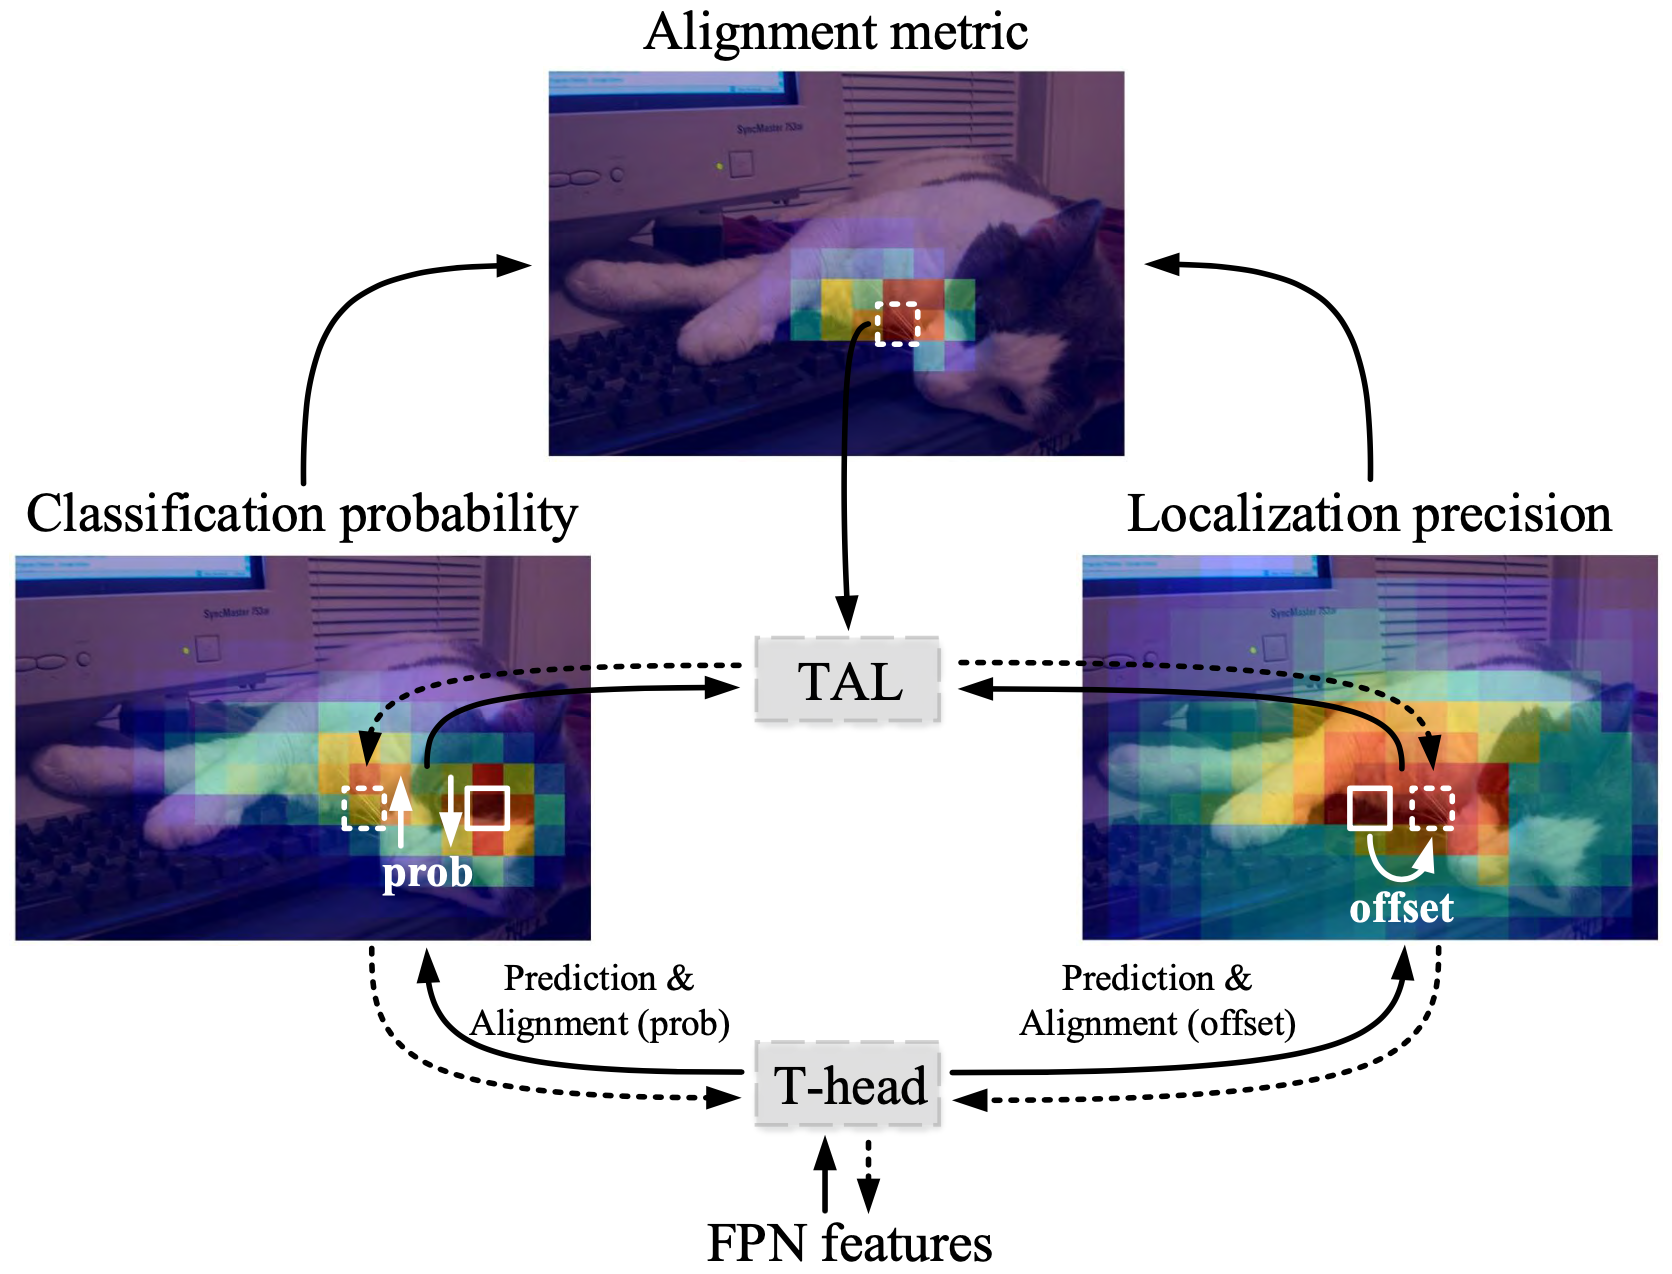
A task-aligned one-stage detector that explicitly aligns classification and localization and has been widely adopted by YOLO-family detectors.
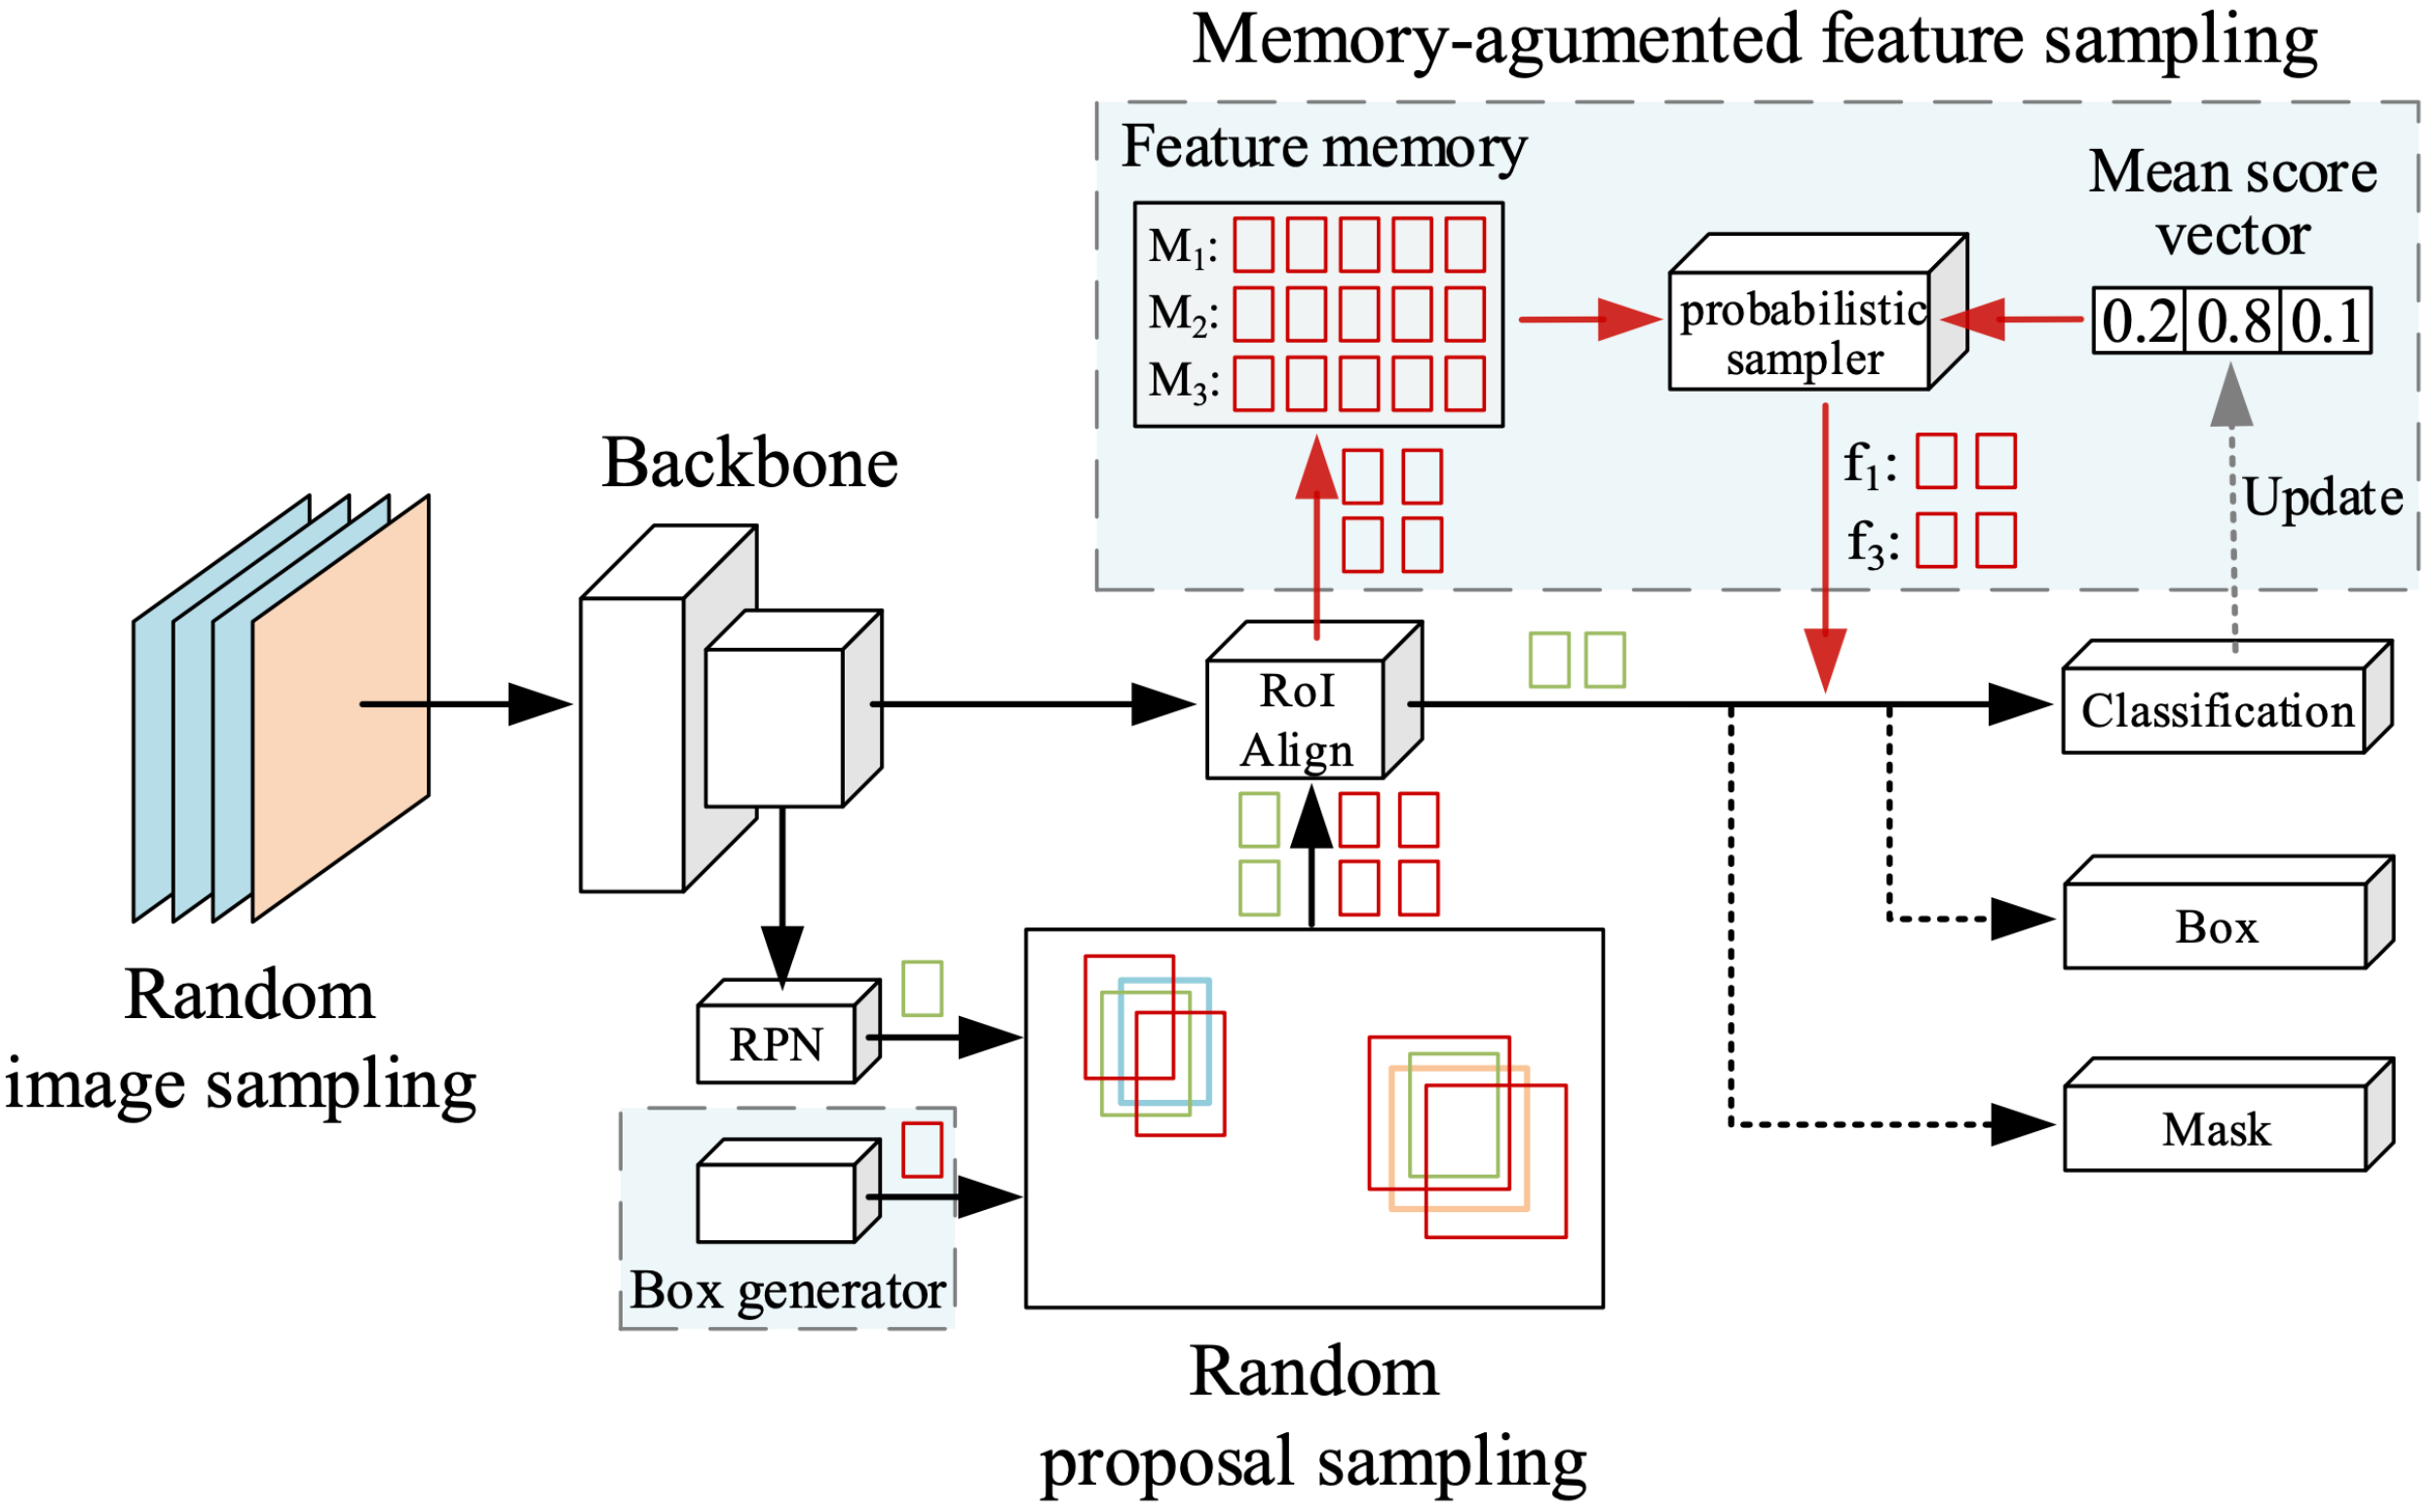
A long-tailed object detection method that balances classification with Equilibrium Loss and Memory-augmented Feature Sampling.
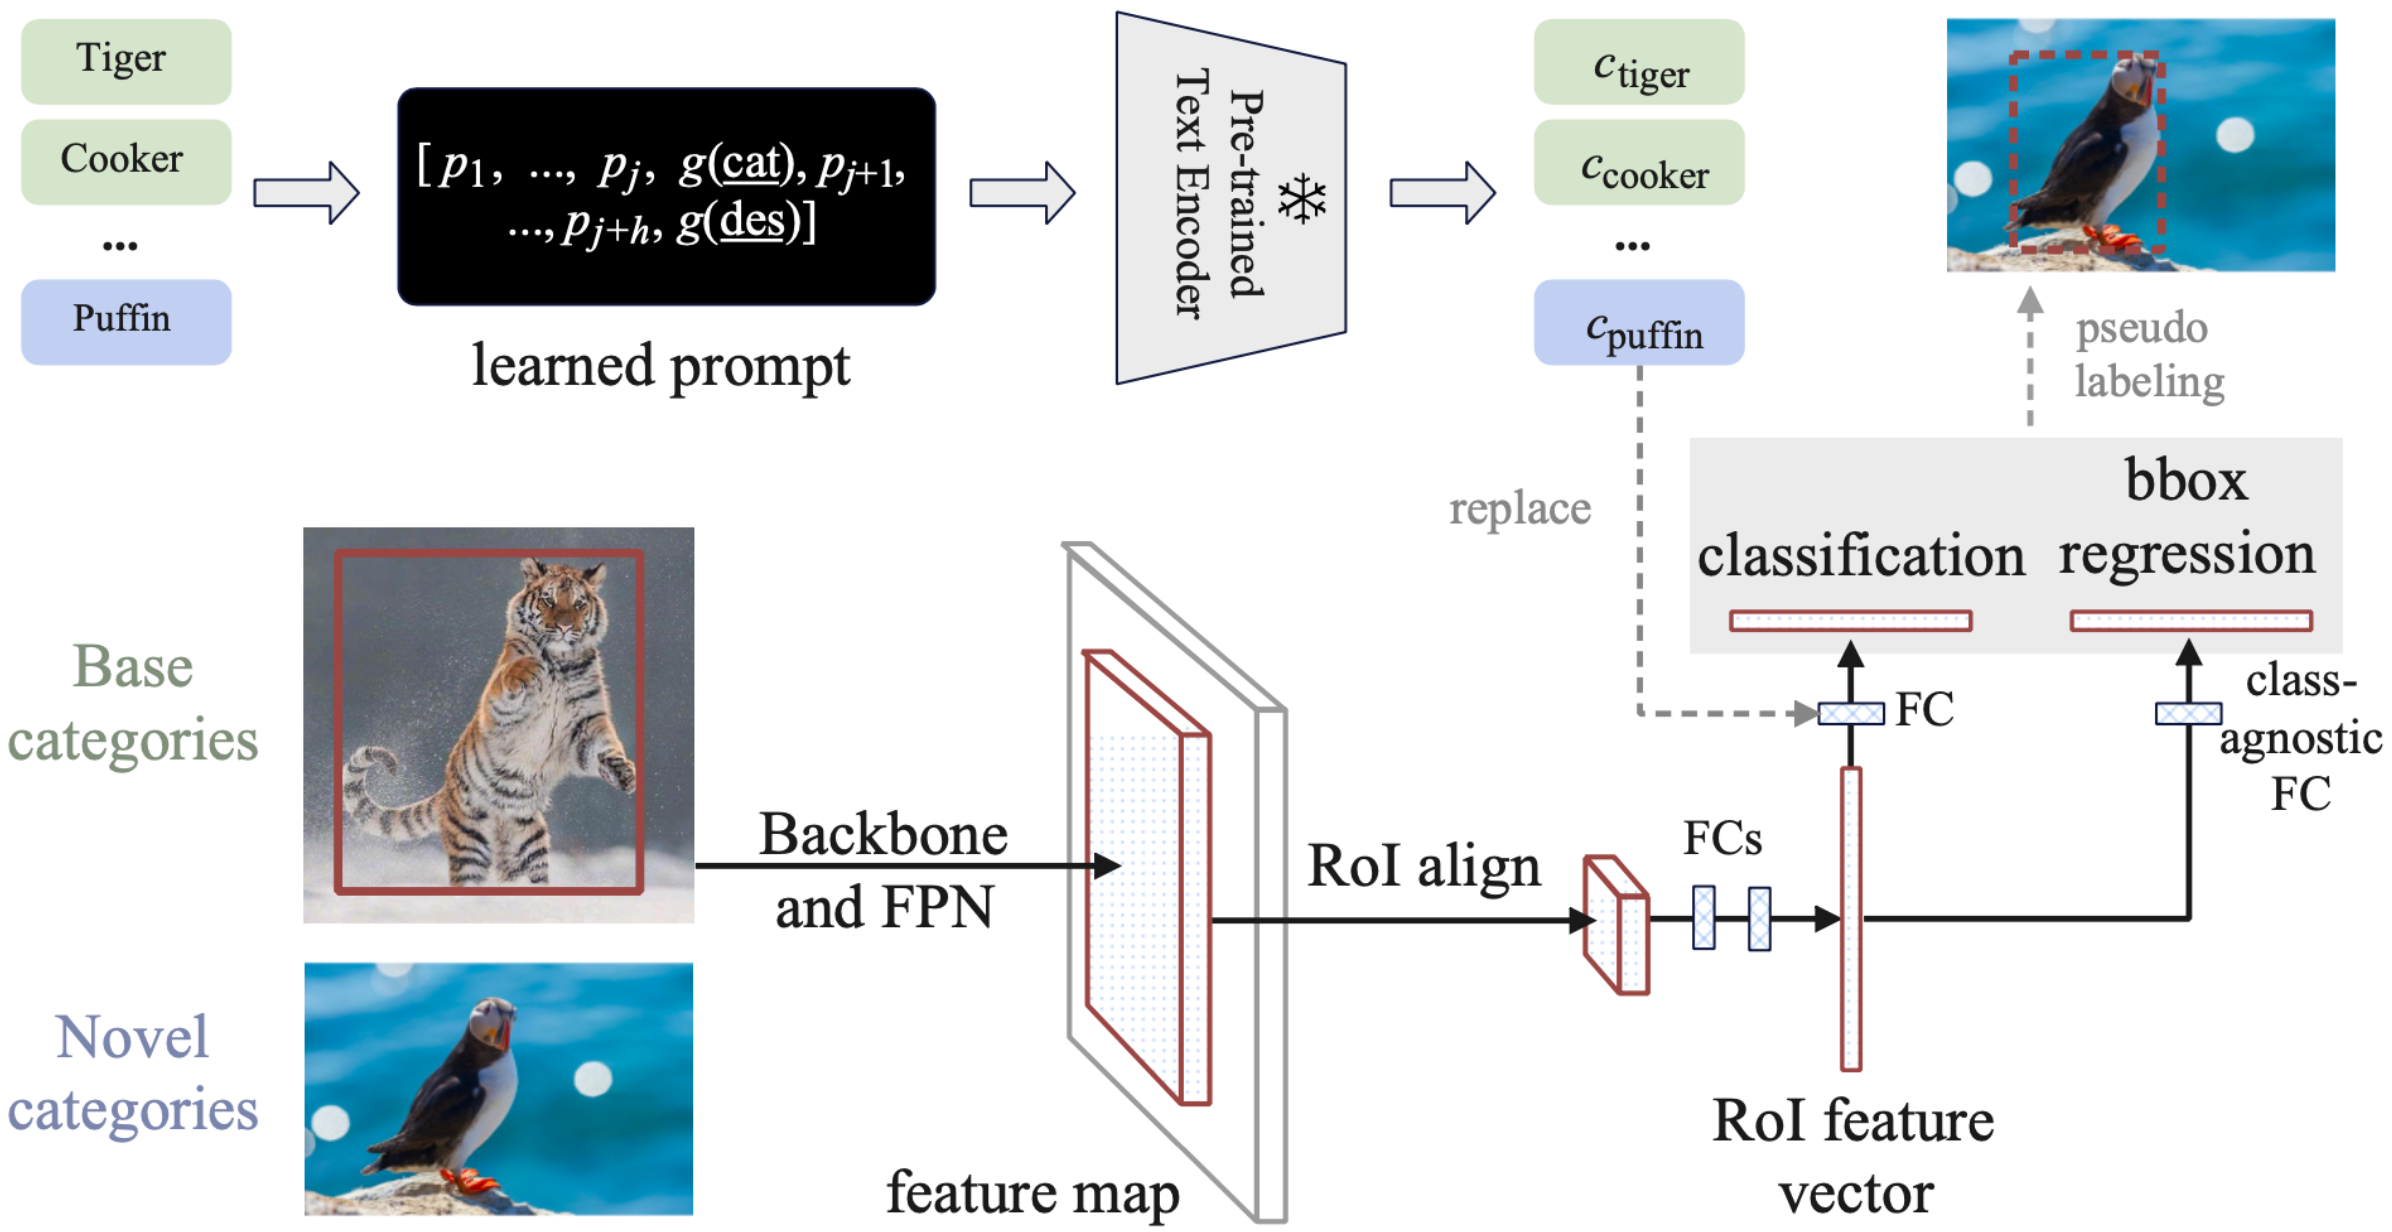
An open-vocabulary object detector that learns from uncurated images and detects novel categories without manual annotations.
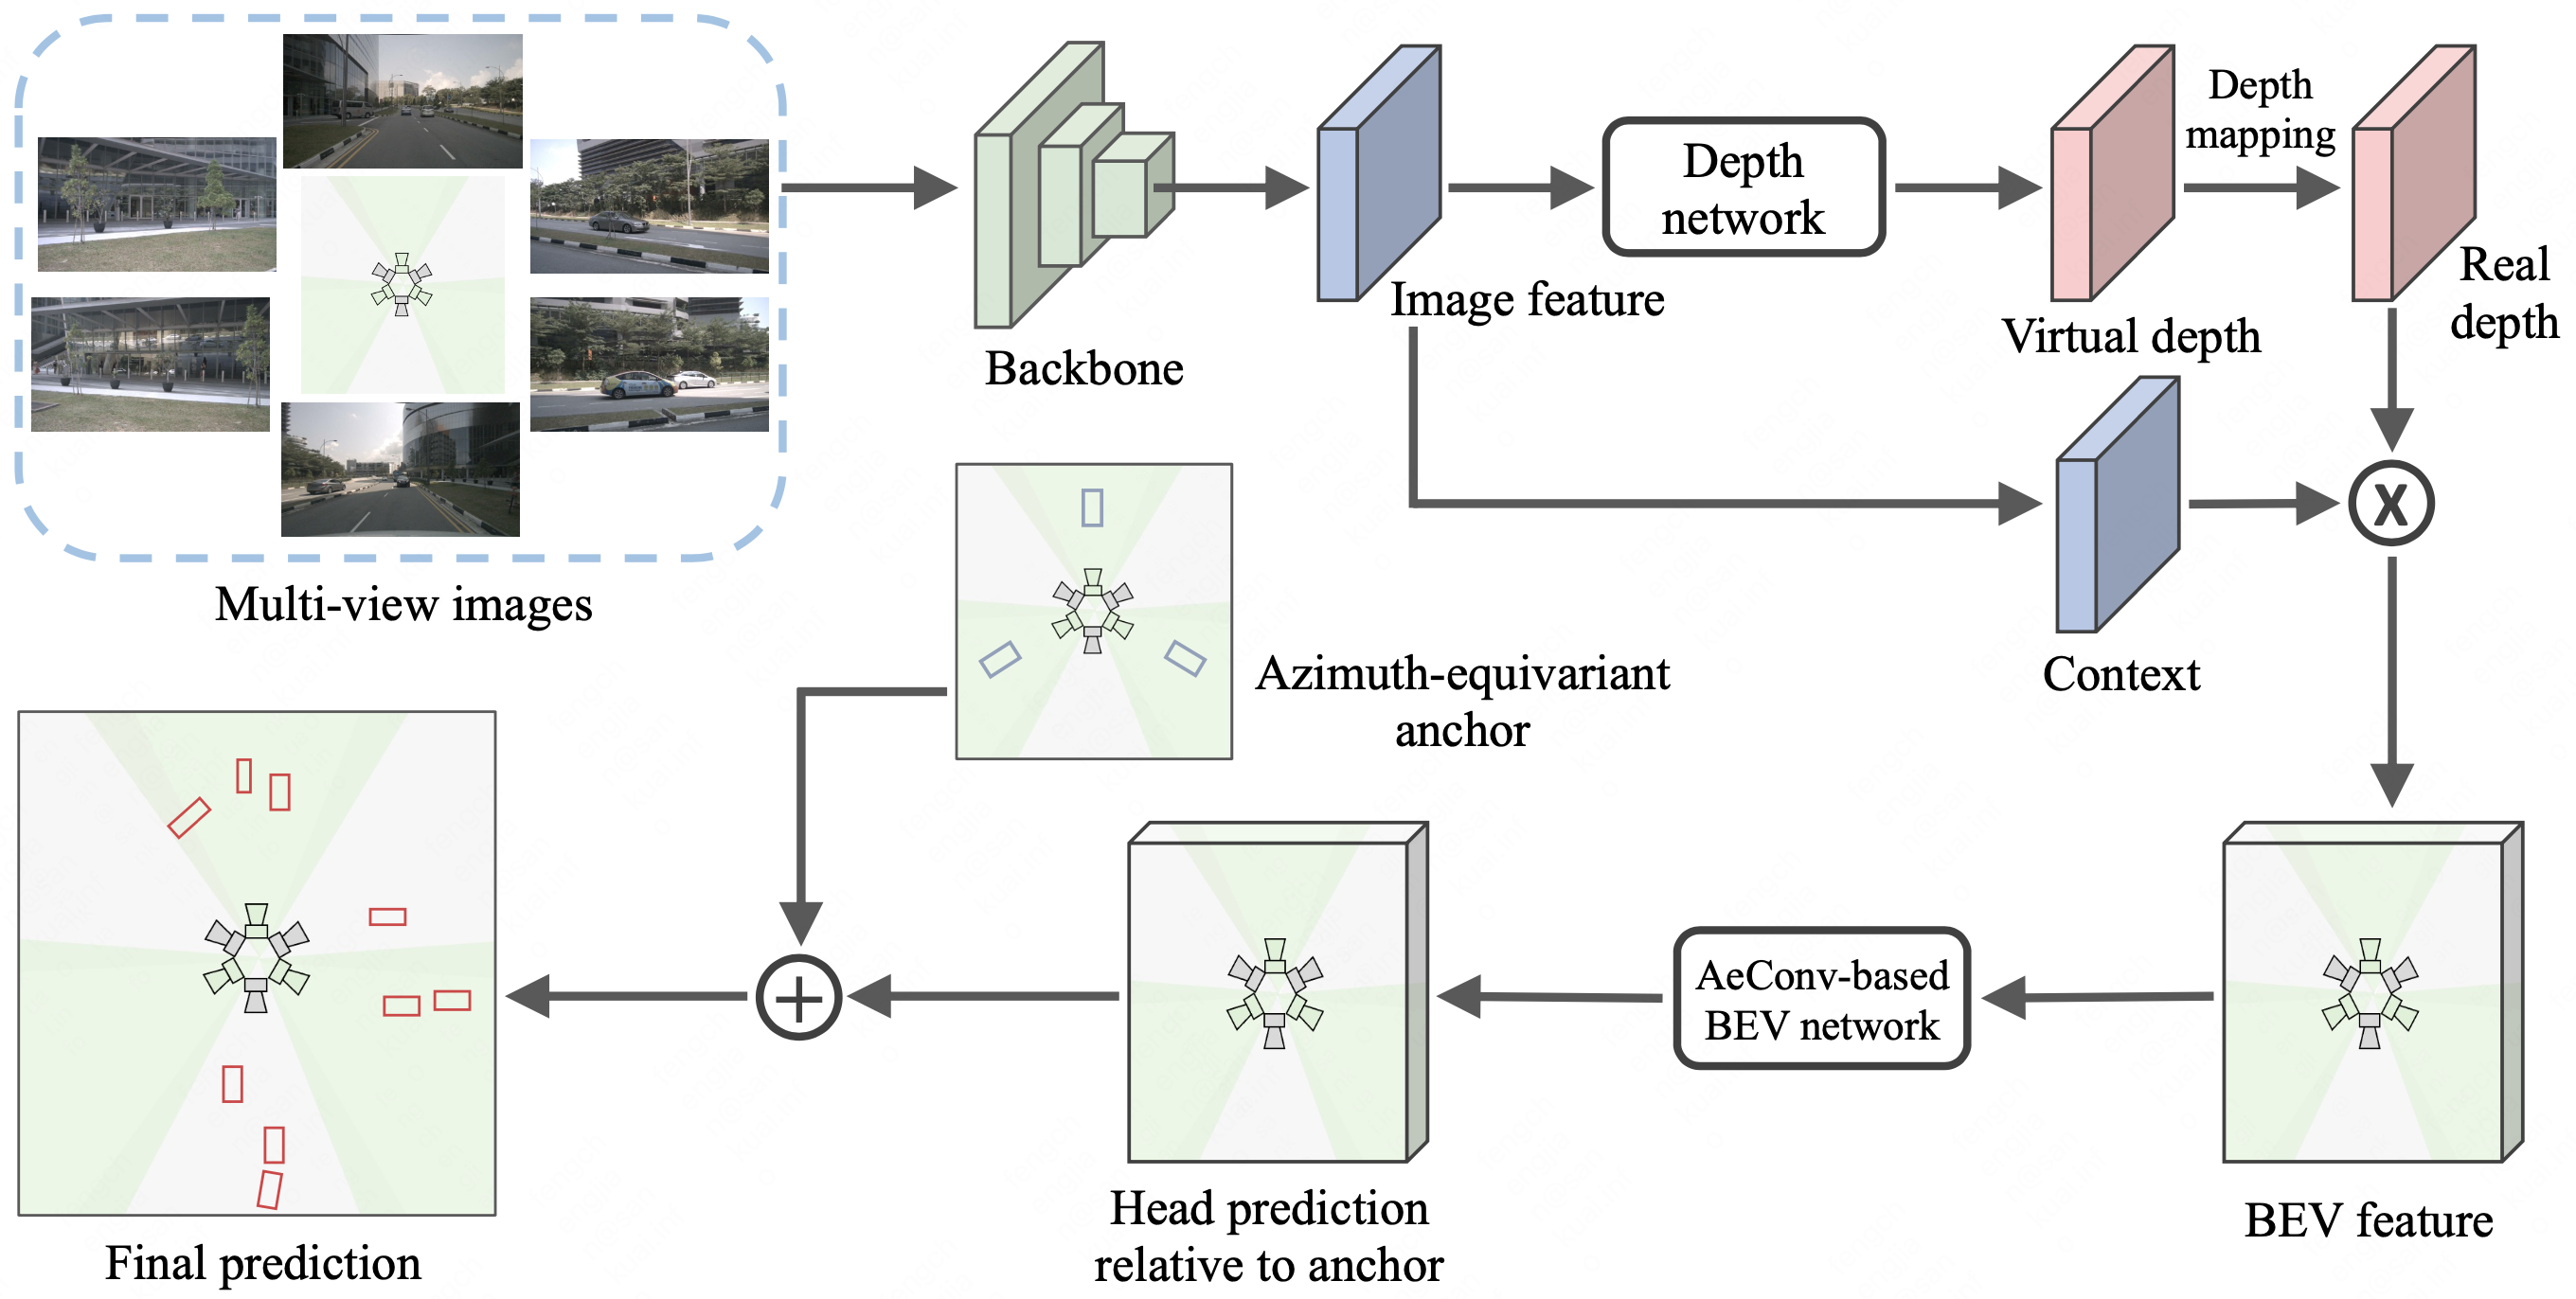
An azimuth-equivariant multi-view 3D detector that preserves BEV radial symmetry with AeConv and improves robustness across camera orientations.
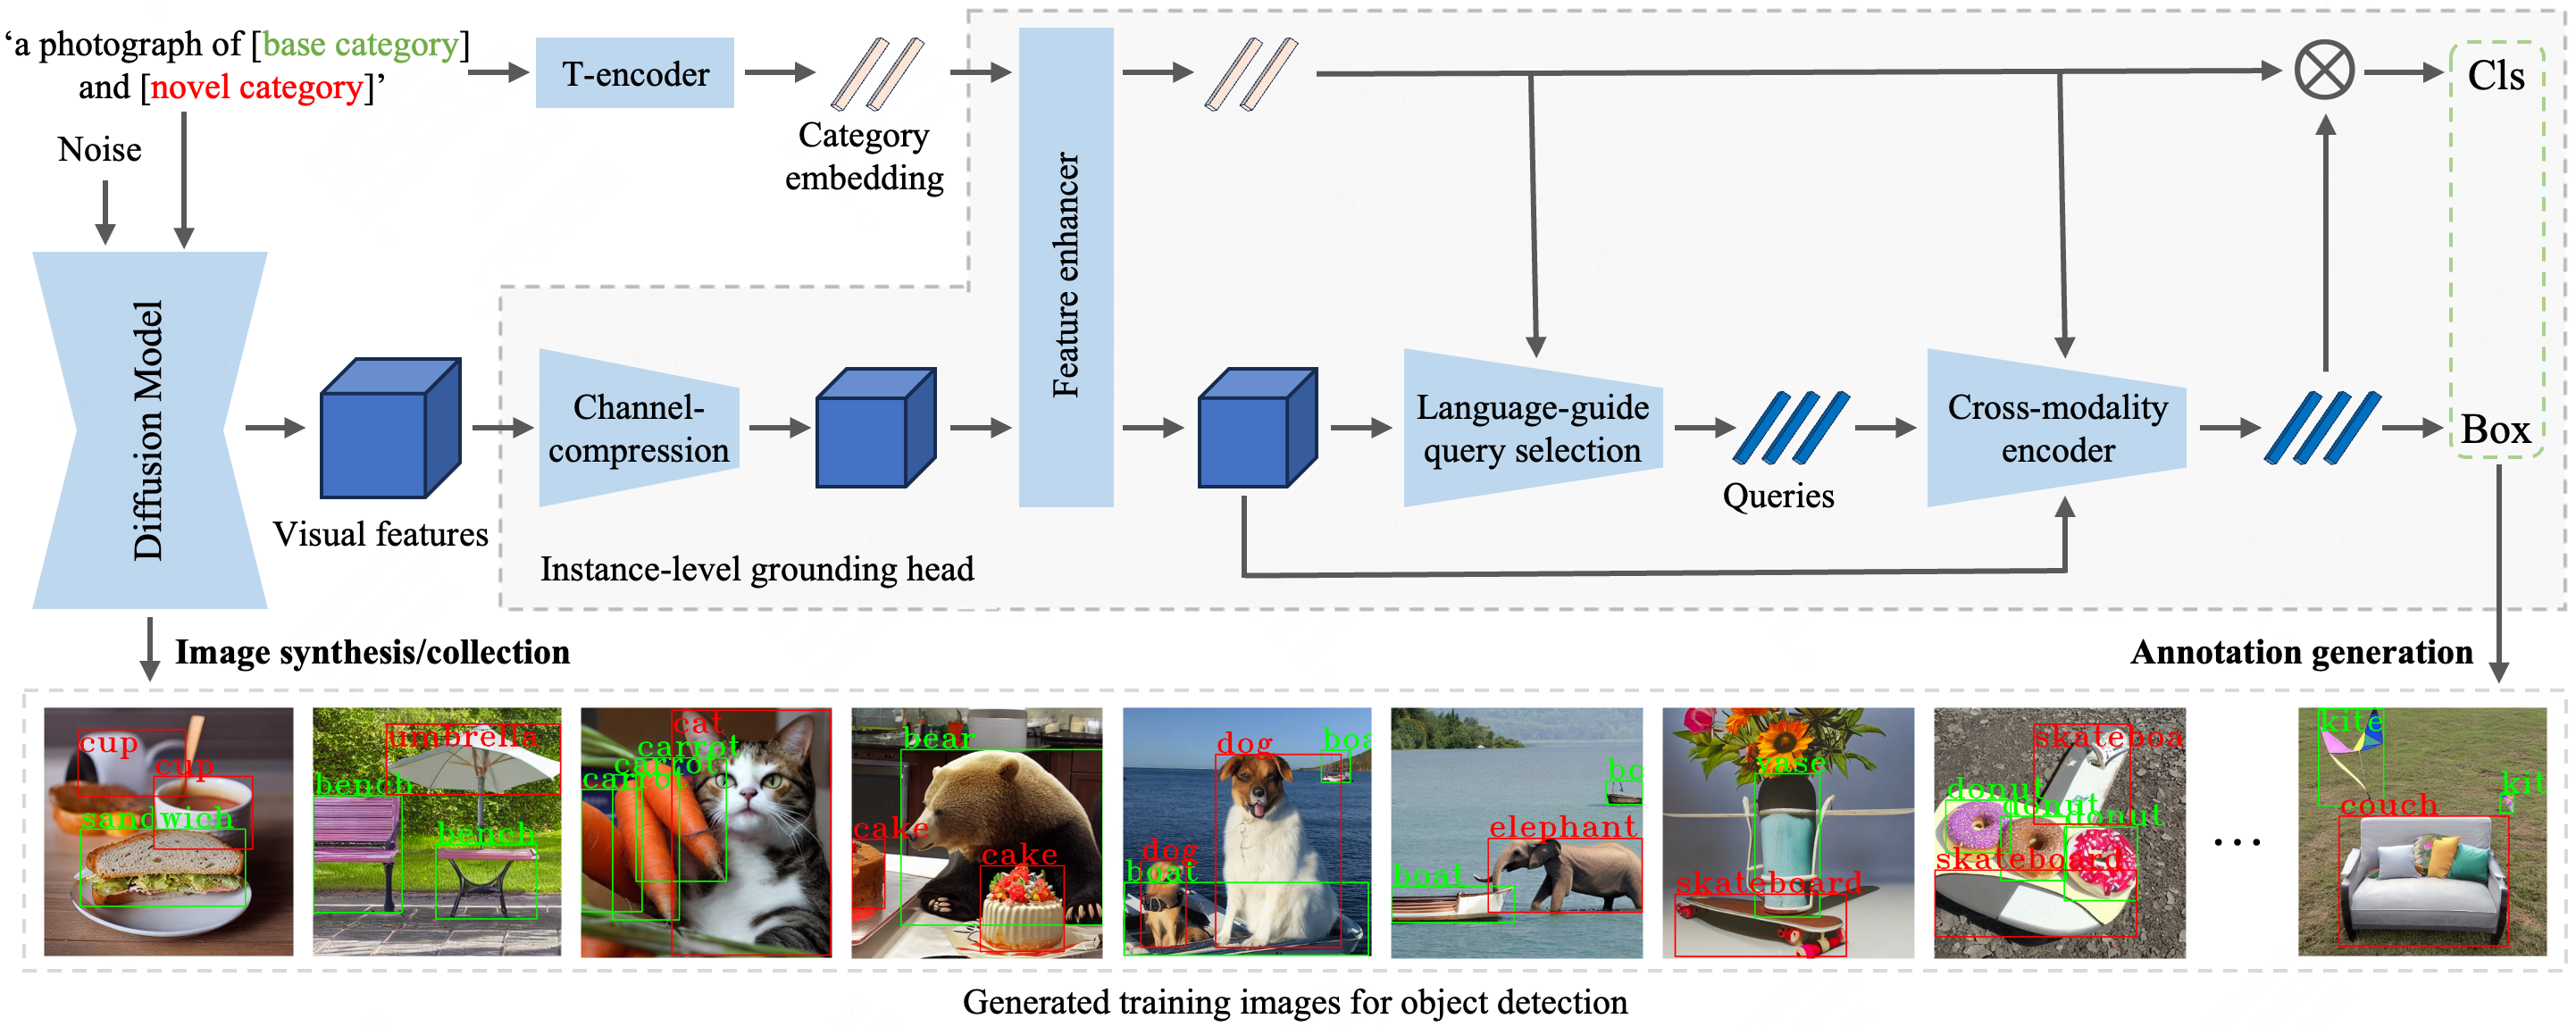
A synthetic-data training paradigm that adds instance-level grounding to diffusion models for open-vocabulary and data-sparse object detection.
For a more complete list of publications and research activities, please refer to my Google Scholar profile.